moondream
R2026bDescription
Add-On Required: This feature requires the Computer Vision Toolbox Model for Moondream Vision Language Model add-on.
The moondream object configures a pretrained Moondream™
vision-language model (VLM).
Moondream is a compact multimodal model that combines visual understanding with natural language processing to perform multiple computer vision tasks. Use the Moondream model to quickly understand image content by generating descriptive captions and detect or localize objects through natural‑language queries, without prior training data. You can also use it to extract printed or handwritten text from images using optical character recognition (OCR) and answer questions about the visual content of an image through visual question answering (VQA). Due to its lightweight design and on-device execution capability, you can use Moondream for low-latency tasks such as alt-text generation, image-text retrieval, scene understanding, object localization, and text extraction.
Creation
Description
Input Arguments
Properties
Object Functions
captionImage | Caption images using Moondream vision-language model (VLM) |
detectObjects | Detect objects in image using Moondream vision-language model (VLM) |
ocrMoondream | Recognize text in image using Moondream vision-language model (VLM) |
queryImage | Query image using Moondream vision-language model (VLM) |
Examples
Load a pretrained Moondream vision-language model with approximately 1.6 billion parameters into the workspace.
mdModel = moondream("moondream-1.6B");Load an image to caption into the workspace, and display the image.
I = imread("peppers.png");
imshow(I)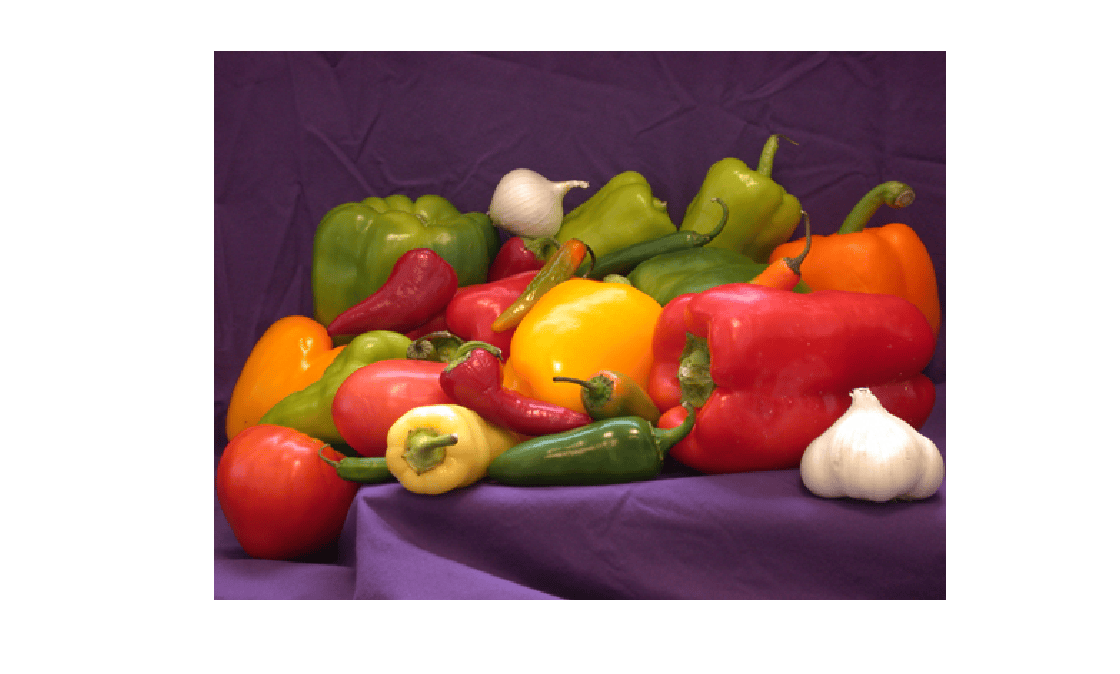
Caption the image using the captionImage object function.
captions = captionImage(mdModel,I);
Display the generated image caption.
display(captions)
captions =
" A purple tablecloth holds a vibrant array of red, green, yellow, and white peppers, onions, and garlic, arranged in a visually appealing composition."
Tips
The quality of Moondream outputs can vary across different data domains. Validate its predictions using a data set from a domain similar to your intended application.
Object detection, OCR, and VQA accuracy can degrade in low-light, heavily occluded, or cluttered scenes. For best results, use high-quality, well-lit images.
References
[1] “Moondream.” Accessed September 2, 2025. https://moondream.ai/.
Version History
Introduced in R2026aSee Also
captionImage | detectObjects | ocrMoondream | queryImage | clipNetwork | visionTransformer

